
German Stata Conference 2024
Bericht zur German Stata Conference 2024
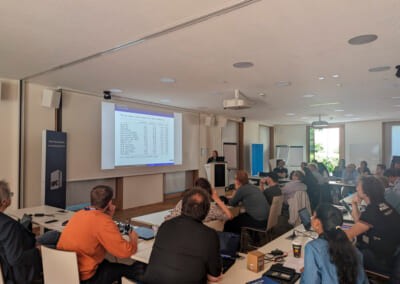
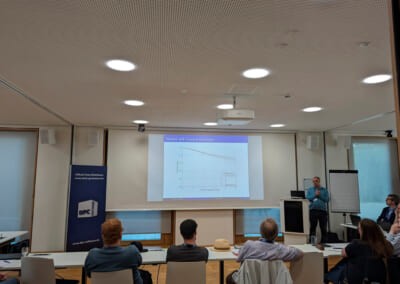
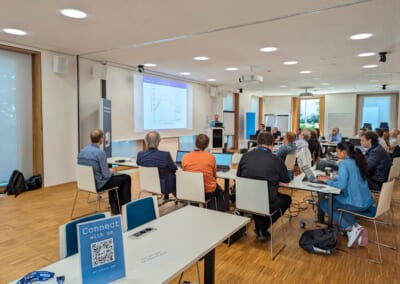
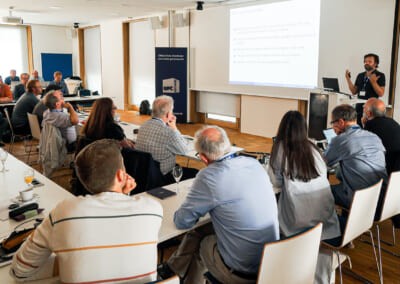
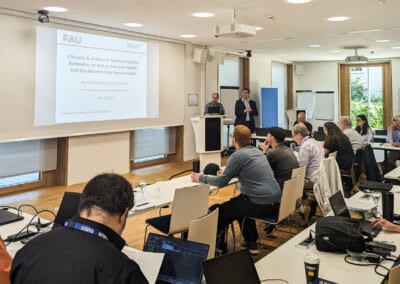
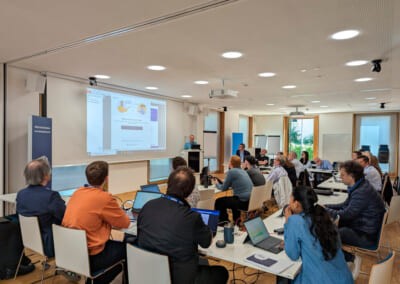
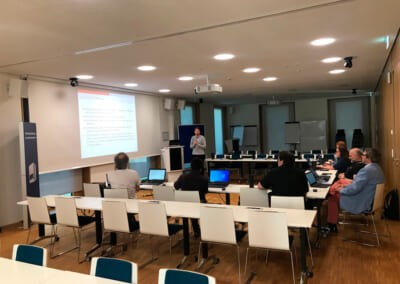
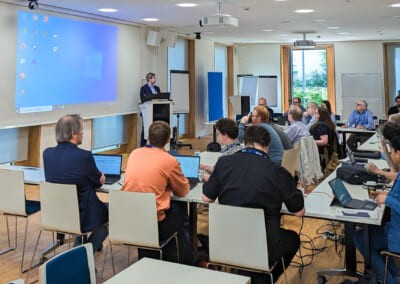
Die diesjährige German Stata Conference fand am 7. und 8. Juni am GESIS – Leibniz-Institut für Sozialwissenschaften in Mannheim statt.
Prof. Reinhard Pollack, Leiter der Abteilung Daten und Forschungsdaten zur Gesellschaft, war Gastgeber der Konferenz, während das DPC-Team für die Organisation verantwortlich war. GESIS ist eine der größten Forschungseinrichtungen Europas im Bereich der sozialwissenschaftlichen Dateninfrastruktur und damit ein idealer Partner für Stata. Prof. Johannes Giesecke (Humboldt-Universität zu Berlin) und Prof. Ulrich Kohler (Universität Potsdam) bildeten das wissenschaftliche Komitee. Als Vertreter von StataCorp durften wir Kristin MacDonald und Chinh Nguyen begrüßen. Das DPC-Team und die Konferenzteilnehmenden nutzten die Gelegenheit, verschiedene Fragen rund um Stata direkt mit den Entwicklern zu diskutieren.
Am Donnerstag fand ein sehr gelungener Pre-Conference-Workshop zur Difference-in-Differences-Schätzung (DiD) statt. Felix Knauf von Sciences Po in Paris stellte die neuesten Entwicklungen dieser Methode vor. Als Experte auf diesem Gebiet hat er gemeinsam mit Kollegen verschiedene benutzerdefinierte Ado-Programme entwickelt, die er in seinem siebenstündigen Workshop ausführlich erläuterte. Die Teilnehmenden konnten die Methoden praktisch anwenden und konkrete Fragestellungen ausführlich mit Felix diskutieren. Er behandelte die theoretischen Grundlagen der Methode, verschiedene DiD-Ansätze und -Designs sowie aktuelle wissenschaftliche Arbeiten zur Weiterentwicklung der Methode. Darüber hinaus stellte Felix verschiedene webbasierte Ressourcen zur DiD-Schätzung vor.
Die Konferenz begann am Freitag mit einer Vorstellung von GESIS durch Prof. Pollack. Darauf folgte die Keynote von Prof. Paul Lambert (University of Leicester und Karolinska Institutet, Stockholm) zum Thema Survival Analysis (Ereigniszeitanalyse). Er sprach sich für flexible parametrische Überlebenszeitmodelle als Alternative zum „Goldstandard“, dem Cox-Proportional-Hazards-Modell, aus. In diesem Zusammenhang stellte er sein benutzerdefiniertes Ado-Programm stpm3 sowie verschiedene Postestimation-Tools vor.
Ebenfalls mit der Überlebenszeitanalyse befasste sich der zweite Vortrag von Prof. Harald Tauchmann (Friedrich-Alexander-Universität Erlangen-Nürnberg). Er präsentierte seine benutzerdefinierten Ado-Programme cfbinout und xtdhazard. Beide Vorträge griffen aktuelle Diskussionen auf dem Gebiet der Überlebenszeitanalyse auf.
Die letzten beiden Vorträge vor der Mittagspause hielten Peter Krause (DIW Berlin) zum Thema mehrdimensionale Wohlfahrt, Deprivation und Ungleichheit sowie Wolfgang Langer (Martin-Luther-Universität Halle-Wittenberg) zu Modellgütemaßen für logistische Regressionsmodelle. Langer entwickelte ein eigenes Programm, mit dem sich verschiedene Pseudo-R²-Statistiken zur Beurteilung der Modellgüte nichtlinearer Modelle berechnen lassen. Im Anschluss entwickelte sich eine lebhafte und kontroverse Diskussion über die Aussagekraft der verschiedenen Maße, da bislang kein allgemein anerkannter Standard etabliert ist. Das benutzerdefinierte Ado-Programm fit_cmlogit leistet einen Beitrag zur laufenden Debatte darüber, wie die Modellgüte logistischer Regressionsmodelle beurteilt werden sollte.
Nach der Mittagspause stellte Kristin MacDonald von StataCorp die aktuellen Stata-Befehle zur individuellen Gestaltung von Tabellen vor. Dazu gehören der überarbeitete Befehl table sowie etable und dtable. Diese Befehle sind benutzerfreundliche Schnittstellen zur neuen, umfangreichen Collect-Befehlssuite. Sie ermöglicht es, statistische Tabellen zusammenzustellen, nach individuellen Anforderungen anzupassen und in Formate wie MS Word, Excel, HTML, LaTeX oder PDF zu exportieren.
Der Export von Tabellen aus Stata in andere Formate stellte über viele Jahre hinweg eine Herausforderung dar und führte zur Entwicklung verschiedener benutzerdefinierter Ado-Programme, darunter esttab und estout. Mit der komplexen Collect-Befehlssuite und den leichter zugänglichen Befehlen table, dtable und etable schließt Stata eine wichtige Lücke im eigenen Befehlsangebot. Dadurch wird die Erstellung und der Export von Tabellen aus Stata in Textverarbeitungsprogramme deutlich erleichtert.
Anschließend stellte Prof. Ben Jann (Universität Bern, Schweiz) sein umfangreiches Ado-Programm geoplot vor. Damit lassen sich Karten in Stata auf Basis standardisierter Shape-Dateien und anderer Formate erstellen. Shape-Dateien enthalten Vektordaten und sind für zahlreiche geografische Gebiete verfügbar. In Kombination mit Datensätzen ermöglicht der Befehl geoplot, Kartengrafiken auf Grundlage verfügbarer räumlicher Daten zu erzeugen. Prof. Janns Vortrag richtete sich nicht nur an Statistikexperten, sondern zeigte auch vielfältige Anwendungsmöglichkeiten für unterschiedliche wissenschaftliche Disziplinen auf.
Ein Thema, das seinen Ursprung in der Replikationskrise der Psychologie hat, ist die Frage, wie sich die Reproduzierbarkeit wissenschaftlicher Ergebnisse sicherstellen lässt. Diese Fragestellung gewinnt in allen wissenschaftlichen Disziplinen an Bedeutung, da die zunehmende Komplexität von Datensätzen und statistischen Methoden die Reproduktion wissenschaftlicher Ergebnisse immer schwieriger macht. Das stellt das Wissenschaftssystem als Ganzes vor Herausforderungen, da die Reproduzierbarkeit für die wissenschaftliche Erkenntnisgewinnung von zentraler Bedeutung ist.
Daniel Krähmer (Ludwig-Maximilians-Universität München) stellte seinen Befehl repreport vor. Ähnlich einer klassischen Log-Datei sammelt dieser während einer laufenden Analyse automatisch Informationen, um gezielt diejenigen Angaben zusammenzustellen, die für die Reproduktion einer Studie erforderlich sind. Dieser Vortrag setzte wichtige Impulse für ein Thema, das unbedingt weiterverfolgt und ausgebaut werden sollte, da es für die Integrität wissenschaftlicher Forschung in allen Disziplinen von großer Bedeutung ist.
In eine ähnliche Richtung ging der Vortrag von Maarten Buis, der eine Reihe von Befehlen (mkproject und boilerplate) entwickelt hat, um Analyseprozesse zu standardisieren. Auch dies steht im Zusammenhang mit der Reproduzierbarkeit wissenschaftlicher Ergebnisse, denn die zunehmende Individualisierung von Forschungsprozessen kann deren Reproduzierbarkeit ebenfalls erschweren.
Der letzte Vortrag der Konferenz widmete sich einem weiteren grundlegenden Thema, das für viele Forschende relevant ist: Datenstrukturen und die Übertragung zwischen verschiedenen Datenstrukturen. Daniel Schneider (Max-Planck-Institut für demografische Forschung, Rostock) wollte eine Diskussion darüber anstoßen, wie sich die Möglichkeiten von Stata in diesem Bereich besser nutzen lassen.
Zusammenfassend lässt sich feststellen, dass die diesjährige Stata Conference zahlreiche übergreifende Fragestellungen und weniger ausschließlich spezifische Themen behandelte. Insbesondere die Reproduzierbarkeit wissenschaftlicher Ergebnisse ist für alle Forschungsdisziplinen von großer Bedeutung und sollte daher auch künftig einen festen Platz in der wissenschaftlichen Diskussion einnehmen.

Professor Paul C. Lambert
Professor für Biostatistik
Paul Lambert ist Professor für Biostatistik an der University of Leicester in Großbritannien und am Karolinska Institutet in Schweden. Seine Forschungsschwerpunkte liegen im Bereich der Überlebenszeitanalyse in der Epidemiologie, insbesondere bei populationsbasierten Krebsstudien. Er hat verschiedene Stata-Befehle entwickelt, vor allem für die Überlebenszeitanalyse. Weitere Informationen: https://pclambert.net/#software
Referent
Felix Knauf
SciencesPo, Paris – Fachbereich Wirtschaftswissenschaften
Felix Knauf absolvierte sowohl seinen Bachelor- als auch seinen Masterabschluss in Wirtschaftswissenschaften an der Universität Mannheim und schloss beide Studiengänge im vergangenen Sommer erfolgreich ab. Während dieser Zeit arbeitete er außerdem als wissenschaftlicher Mitarbeiter an der Universität Mannheim sowie zunächst als Praktikant und später als wissenschaftlicher Mitarbeiter am Institut für Arbeitsmarkt- und Berufsforschung (IAB) in Nürnberg.
Seit September 2023 arbeitet er in Vollzeit als wissenschaftlicher Mitarbeiter für Professor Clément de Chaisemartin an Sciences Po. Dort beschäftigt er sich hauptsächlich mit der Implementierung verschiedener DiD-Schätzverfahren zur Bestimmung kausaler Behandlungseffekte in Form von Stata-Paketen sowie mit der Nutzerunterstützung für die entsprechenden Befehle.
Themen
- Kurze Einführung in DiD und TWFE: Anwendung in Stata anhand einfacher Beispiele mit didregress, xtreg und reghdfe
- Was identifiziert TWFE und wann kann dies problematisch sein? Kurze Einführung in twowayfeweights
- Neue DiD-Methoden, die gegenüber heterogenen Behandlungseffekten robust sind: statische und dynamische Ansätze, gegebenenfalls auch bei kontinuierlichen Behandlungen
- Ausführliche interaktive Sitzung zur Implementierung entsprechender Befehle: did_multiplegt_dyn, csdid, eventstudyinteract und did_imputation, mit besonderem Fokus auf did_multiplegt_dyn
Vorträge
Paul Lambert (University of Leicester, UK and Karolinska Institutet, Sweden)
Abstract: Flexible parametric survival models are an alternative to the Cox proportional hazards model and more standard parametric models for the modelling of survival (time-to-event) data. They are flexible in that spline functions are used to model the baseline and potentially complex time-dependent effects. I will give a brief overview of the models and the advantages over the Cox model. However, I will concentrate on some recent developments. This will include the motivation for developing a new command to fit the models (stpm3), which makes it much simpler to fit more complex models with non-linear functions, non-proportional hazards and interactions and simplifies and extends postestimation predictions, particularly marginal (standardized) predictions. I will also describe some new postestimation tools that help in the evaluation of model fit and validation in prognostic models.
Harald Tauchmann (FAU Erlangen-Nurenberg) and Elena Yurkevich (FAU Erlangen-Nurenberg)
Abstract: We introduce the new community-contributed Stata commands cfbinout and xtdhazard. The former generalizes ivprobit, twostep by allowing discrete endogenous regressors and different link functions than the normal link, specifically logit and cloglog. In terms of the underlying econometric theory, cfbinout is guided by Wooldridge (2015). In terms of the implementation in Stata and Mata, respectively, cfbinout follows Terza (2017). xtdhazard is essentially a wrapper for either cfbinout or alternatively ivregress 2sls. When calling ivregress 2sls, xtdhazard implements the linear first-differences (or higher-order differences) instrumental variables estimator suggested by Farbmacher & Tauchmann (2023) for dealing with time-invariant unobserved heterogeneity in the discrete-time hazard model. When calling cfbinout, xtdhazard implements—depending on the specified link function—several nonlinear counterparts of this estimator that are briefly discussed in the online supplement to Farbmacher & Tauchmann (2023). Using xtdhazard—rather than directly using ivregress 2sls, ivprobit, twostep, or cfbinout—simplifies the implementation of these estimators, as generating the numerous instruments required can be cumbersome, especially when using factor-variables syntax. In addition, xtdhazard performs several checks that may prevent ivregress 2sls and ivprobit, twostep, respectively, from failing and reports issues like perfect first-stage predictions. An (extended) replication of Cantoni (2012) illustrates the use of cfbinout and xtdhazard in applied empirical work.
- Cantoni, D. (2012). Adopting a new religion: The case of Protestantism in 16th century Germany, The Economic Journal 122, 502-531.
- Farbmacher, H. and Tauchmann, H. (2023). Linear fixed-effects estimation with nonrepeated outcomes, Econometric Reviews 42(8): 635–654.
- Terza, J. (2017). Two-stage residual inclusion estimation: A practitioners guide to Stata implementation, Stata Journal 17(4): 916–938.
- Wooldridge, J. M. (2015). Control function methods in applied econometrics, The Journal of Human Resources 50(2): 420–445.
Peter Krause (DIW Berlin, SOEP)
Abstract: The presentation offers a brief summary for a set of Stata programs for extended multidimensional applications on well-being, deprivation, and inequality. The first section illustrates the underlaying motivation by some empirical examples on decomposed multi- dimensional results. The second section on multi-dimensional well-being and deprivation measurement illustrates the conceptual background—based on the Alkire/Foster MPI framework (and CPI, N. Rippin)—which is also applied to well-being measurement, and extended by a parameter driven fixed-fuzzy approach—with several illustrations and further details on the options offered in the Stata deprivation and well-being programs. The third section on multi- dimensional inequalities refers to a multidimensional Gini-based row-first measurement framework with a special emphasize on multiple within- and between-group-inequalities—including conceptual extensions on horizontal between-group applications and further details on the options offered in the Stata inequality program. Section four summarizes and opens up for advice and discussion.
Wolfgang Langer (Martin-Luther-University Halle-Wittenberg)
Abstract: McFadden developed the conditional multinomial logit model in 1974 using it for rational choice modeling. In 1993 Stata introduced it in version 3. In 2007 Stata extended this model to the asclogit or ascprobit being able to estimate the effects of alternative-specific and case-specific exogenous variables on the choice probability of the discrete alternatives. In 2021, Stata added the class of choice models extending it to random-effect (mixed) and panel models. As it stands, Stata only provides an post-estimation Wald chi-square test to assess the overall model. However, although McFadden developed an pseudo r-square to assess the fit of the conditonal logit model already in 1974, Stata still does not provide it even in version 18. Thus, I developed fit_cmlogit to calculate the McFadden pseudo r-square using a zero model with alternative-specific constants to correct the uneven distribution of alternatives. Furthermore, it calculates the corresponding Likelihood-Ratio-chi-square test which is more reliable / conservative as the Wald test. The program uses the formulas of Hensher & Johnson (1981) and Ben-Akiva & Lerman (1985) for the McFdden pseudo-r square to correct the number of exogenous variables and faced alternatives. Train (2003) discussed these characteristics of the McFadden pseudo r-square in detail. Additionally it calculates the log-likelihood-based pseudo r-squares developed by Maddala (1983, 1988), Cragg & Uhler (1970) and Aldrich & Nelson (1984). The latter uses the correction formula proposed by Veall & Zimmermann (1994). An empirical example of predicting voting behavior in the German federal election study of 1990 demonstrates the usefulness of the program to assess the fit of logit choice models with alternative-specific and case-specific exogenous variables.
- Aldrich, J.H. & Nelson, F.D. (1984): Linear probability, logit and probit models. Beverly Hills, CA: Sage
- Ben-Akiva, M. & Lerman, S.R. (1985): Discrete choice analysis: Theory and application to travel demand. Cambridge, MA: MIT Press
- Cragg, G. & Uhler, R. (1970): The demand of automobiles. Canadian Journal of Economics, 3, pp.386-406
- Hensher, D.A. & Johnson, L.W. (1981): Applied discrete choice modelling. London: Croom Helm/Wiley
- Domencich, T.A. & McFadden, D. (1975): Urban travel demand. A behavioral analysis. Amsterdam u. Oxford: North Holland Publishing Company
- Maddala, G.S. (1983): Limited-dependent and qualitative variables in econometrics. Cambridge, U.K.: Cambridge University Press
- Maddala, G.S. (1992² (1988)): Introduction to Econometrics. New York, N.Y.: Maxwell
- MacmillanMcFadden, D. (1974): Conditional logit analysis of qualitative choice behavior. In: Frontiers of econometrics. Ed. P. Zarembka,, pp. 105-142. New York: Academic Press
- McFadden, D. (1979): Quantitative methods for analysing travel behaviour of individuals: some recent developments. In: Hensher, D.A.& Stopher, P.R.: (eds): Behavioural travel modelling. London: Croom Helm, pp. 279-318
- Train, K.E. (2003): Discrete choice methods with Simulations. Cambridge, U.K.: Cambridge University Press
- Veall, M.R. & Zimmermann, K.F. (1994): Evaluating Pseudo-R2’s for binary probit models. Quality&Quantity, 28, pp. 151- 164
Kristin MacDonald (StataCorp)
Abstract: Presenting results effectively is a crucial step in statistical analyses, and creating tables is an important part of this step. Whether you need to create a cross-tabulation, a Table 1 reporting summary statistics, a table of regression results, or a highly customized table of results returned by multiple Stata commands, the tables features introduced in Stata 17 and Stata 18 provide ease and flexibility for you to create, customize, and export your tables. In this presentation, I will demonstrate how to use the table, dtable, and etable commands to easily create a variety of tables. I will also show how to use the collect suite to build and customize tables and to create table styles with your favorite customizations that you can apply to any tables you create in the future. Finally, I will demonstrate how to export individual tables to Word, Excel, LaTeX, PDF, Markdown, and HTML and how to incorporate your tables into complete reports containing formatted text, graphs, and other Stata results.
Ben Jann (University of Bern)
Abstract: geoplot is a new command for drawing maps from shape files and other datasets. Multiple layers of elements such as regions, borders, lakes, roads, labels, and symbols can be freely combined and the look of elements (e.g. color) can be varied depending on the values of variables. Compared to previous solutions in Stata, geoplot provides more user convenience, more functionality, and more flexibility. In this talk I will introduce the basic components of the command and illustrate its use with examples.
Daniel Krähmer (Ludwig-Maximilians-Universität München)
In theory, Stata provides a stable computational environment and includes commands (i.e., version) that are specifically designed to ensure reproducibility. In practice, however, users often lack the time or the knowledge to exploit this potential. Insights from an ongoing research project on reproducibility in the social sciences show that computational reproducibility is regularly impeded by researchers being unaware what files (i.e., datasets, do-files), software components (i.e., ados), infrastructure (i.e., directories), and information (i.e., ReadMe files) is needed to enable reproduction. This presentation introduces the new Stata command repreport as a potential remedy. The command works like a log, with one key difference: Instead of logging the entire analysis, repreport extracts specific pieces of information pertinent to reproduction (e.g., names and locations of datasets, ados, etc.) and compiles them into a concise reproduction report. Furthermore, the command includes an option for generating a full-fledged reproduction package containing all components needed for push-button reproducibility. While repreport adds little value for researchers whose workflow is already perfectly reproducible, it constitutes a powerful tool for those who strive to make their research in Stata more reproducible at (almost) no additional cost.
Maarten L. Buis (University of Konstanz)
There is usually a set of commands that are included in every .do file a person makes, like clear all or log using. What those commands are can differ from person to person, but most persons have such a standard set. Similarly, a project usually has a standard set of directories and files. Starting a new .do file or a new project thus involves a number of steps that could easily be automated. Automating has the advantage of reducing the amount of work you need to do. However, the more important advantage of automating the start of a .do file or project is that it makes it easier to maintain your own workflow: it is so easy to start „quick and dirty“ and promise to yourself that you will fix that „later“. If the start is automated, then you don’t need to fix it.
The mkproject command automates the beginning of a project. It comes with a set of templates I find useful. A template contains all the actions (like create sub-directories, create files, run other Stata commands) that mkproject will take when it creates a new project. Since everybody’s workflow is different, mkproject allows users to create their own template. Similarly, the boilerplate command creates a new .do file with boilerplate code in it. It comes with a set of templates, but the user can create their own.
This talk will illustrate the use of both mkproject and boilerpate and how to create your own templates.
Daniel C. Schneider (Max Planck Institute for Demographic Research, Rostock)
This presentation starts out by enumerating and describing the main data structures in Stata (e.g., data sets / frames, matrices) and Mata (e.g., string and numeric matrices, objects like associative arrays). It analyzes ways in which data can be represented and coerced from one data container into another. After assessing the strengths and limitations of existing data containers, it muses on potential additions of new data structures and on enriching the functionality of existing data structures and their interplay. Moreover, data structures from other languages, such as Python lists, are described and examined for their potential introduction into Stata / Mata. The goal of the presentation is to stimulate a discussion among Stata users and developers about ways in which the capabilities of Stata’s data structures could be enhanced in order to ease and open up new possibilities for data management and analysis.