German Stata Conference 2027
CALL FOR PRESENTATIONS
We would like to announce the 24th German Stata Conference to be held Friday, June 4th, 2027 at Humboldt University Berlin.
All Stata users, from Germany and elsewhere, or those interested in learning about Stata, are invited to attend.
Presentations for any skill level are sought on topics that include the following:
-
User-written Stata programs
-
Case studies of research or teaching using Stata
-
Discussions of data management problems
-
Reviews of analytic issues
-
Surveys or critiques of Stata facilities in specific fields and related topics.
The conference language is English, as the event has an international focus and will feature guest speakers from abroad.
Submission of Papers
If you would like to give a presentation, please submit an abstract of no more than 200 words via email to one of the academic organizers. The submission deadline is February 15, 2027. Presentations should not exceed 20 minutes in length.
Registration
Participants are asked to cover their own travel expenses. A small registration fee will be charged to cover meals during the conference, including refreshments and lunch.
On Friday evening, we invite you to join us for an informal dinner at a restaurant in Berlin. You can optionally add this event to your registration for €35 per person. We look forward to a relaxed way to end the day together.
Please register by email, in writing, or by phone with Tim Prenzel.
Dr. Asjad Naqvi
Österreichisches Institut für Wirtschaftsforschung (WIFO)
Vortrag: Visualizing relationships in Stata
Philippe van Kerm
Universität Luxemburg
Vortrag: Shapley value calculations: Implementation and illustrations
Meghan Cain
(StataCorp LLC.) Vortrag: Psychometric meta-analysis
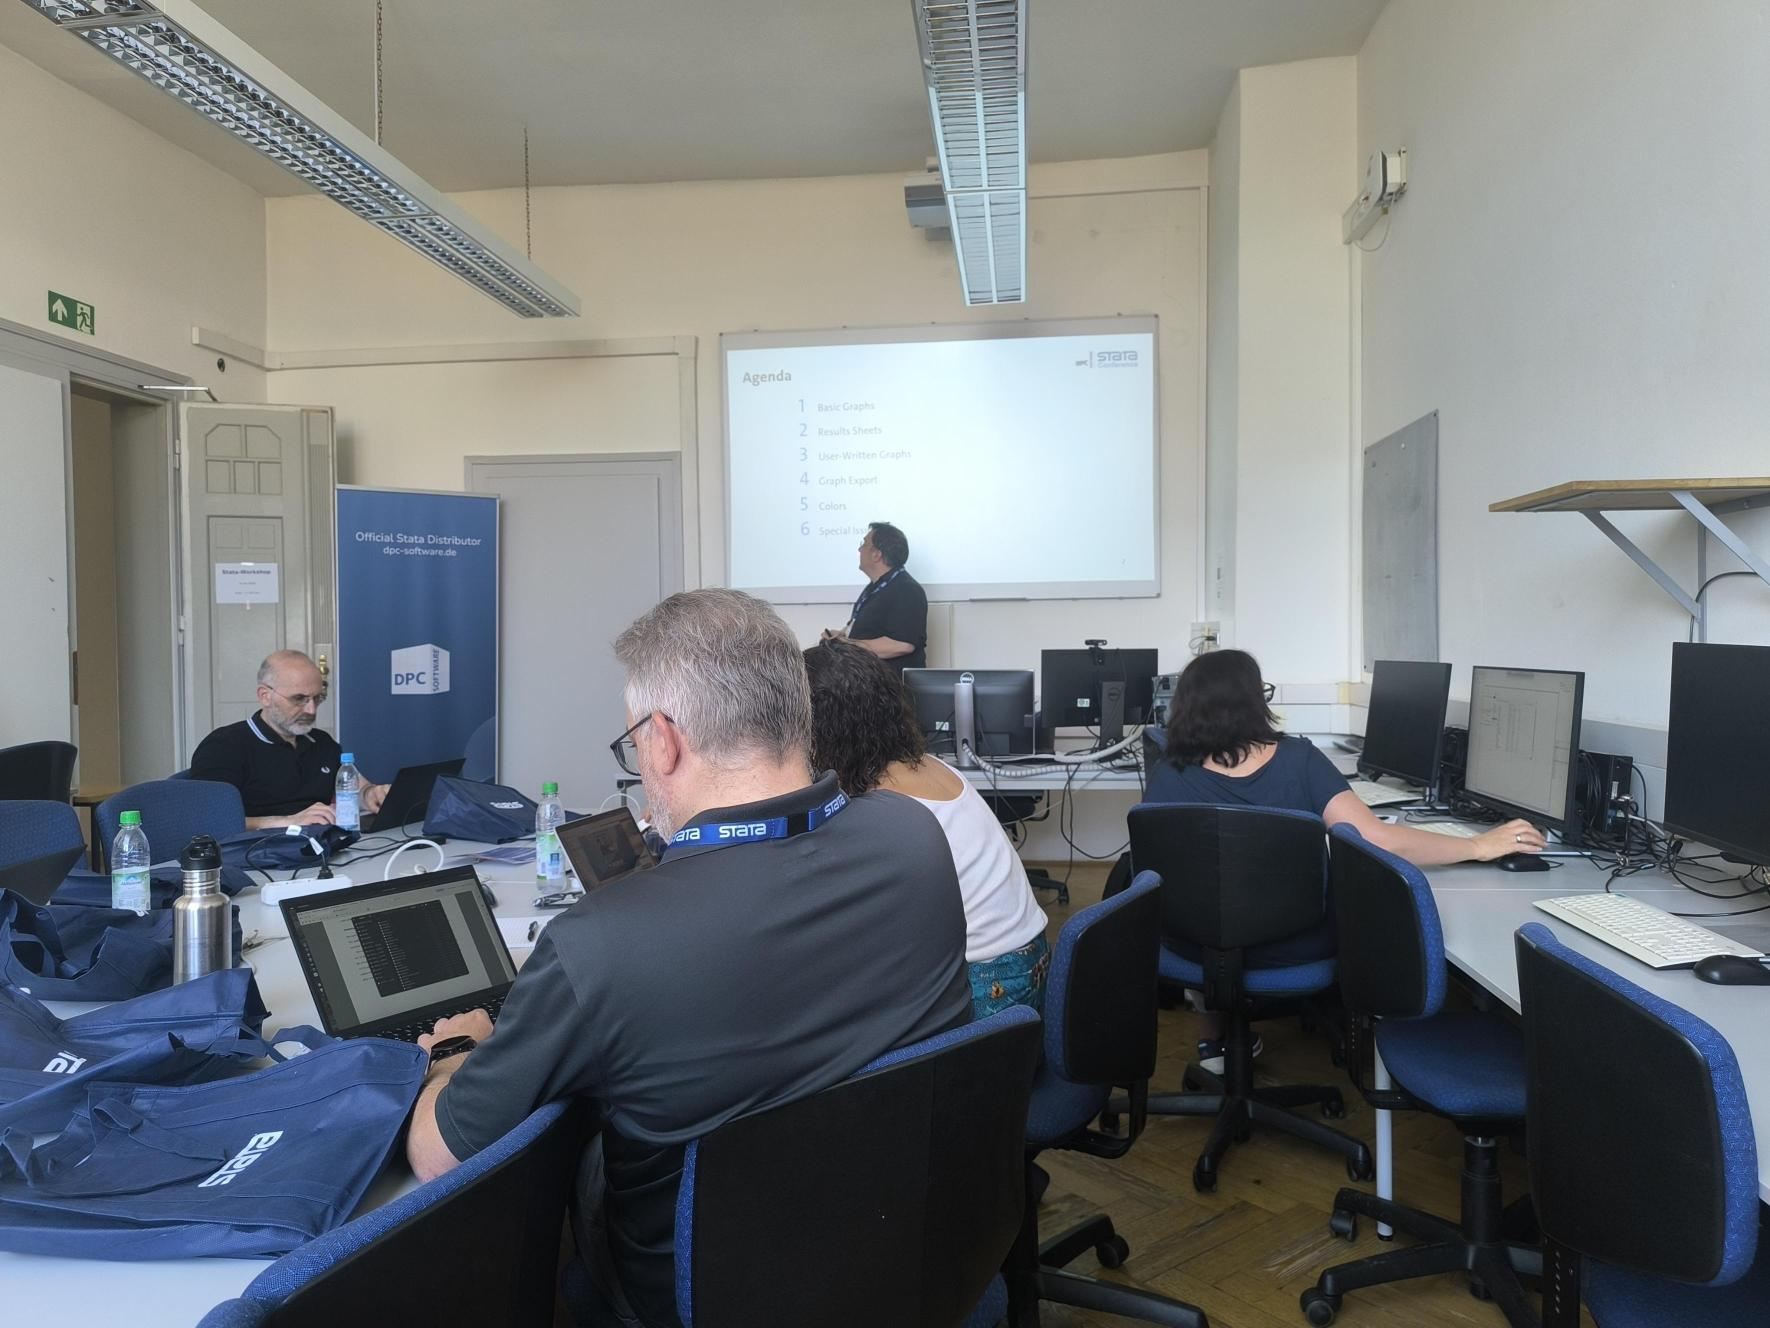
Die Bedeutung visueller Kommunikation nimmt nicht nur in den sozialen Medien, sondern auch in der Forschung stetig zu. Deshalb ist es entscheidend, Ergebnisse in Grafiken und Diagrammen angemessen darzustellen, sodass Lesende die enthaltenen Informationen korrekt erfassen und interpretieren können.
Stata bietet publikationsreife Grafiken, die sich auf vielfältige Weise anpassen lassen. Die Erstellung wissenschaftlicher Publikationen erfolgt jedoch häufig unter hohem Zeitdruck, sodass Forschenden oft nicht genügend Zeit bleibt, ihre Grafiken bis ins letzte Detail zu optimieren.
Der Workshop richtet sich an Studierende und Wissenschaftler unterschiedlicher Erfahrungsstufen. Im Mittelpunkt stehen effiziente Methoden zur Grafikerstellung. Dabei geht es unter anderem darum, systematisch farbige Grafiken zu gestalten, die sich intuitiv erschließen und leicht verstehen lassen.
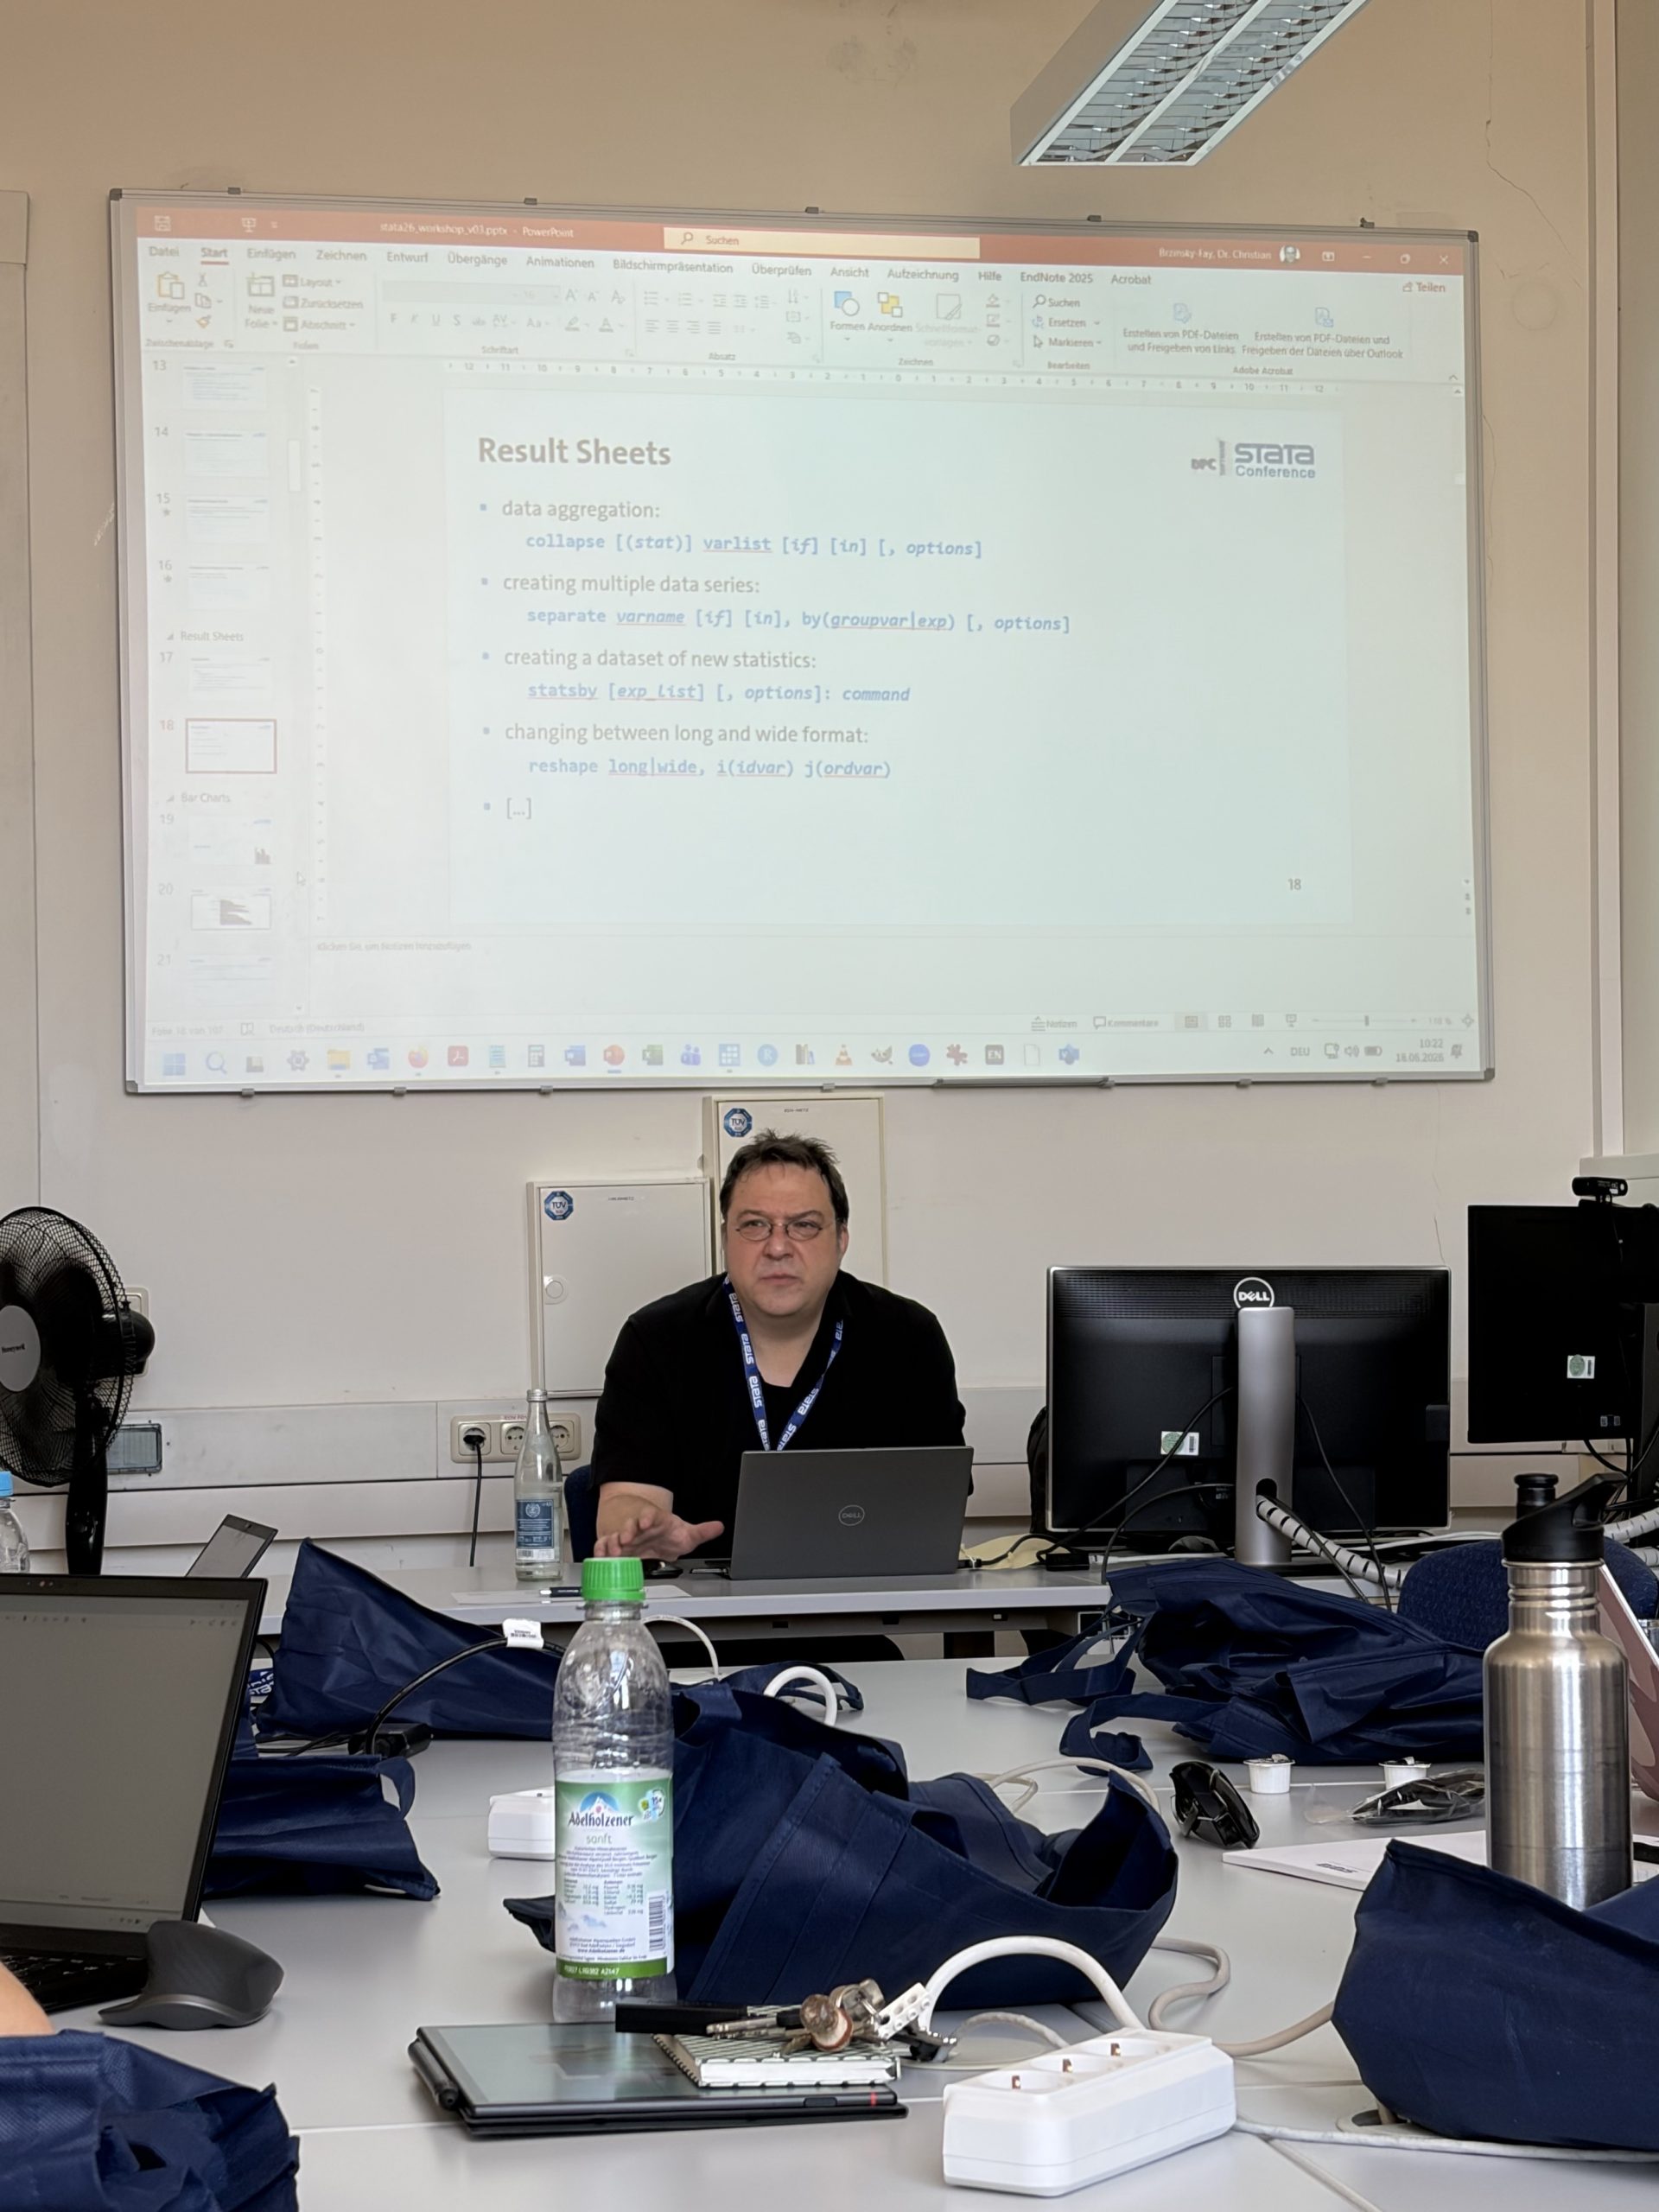
Darüber hinaus werden die nachträgliche Bearbeitung von Grafiken sowie verschiedene hilfreiche Tricks behandelt, die nicht in der offiziellen Dokumentation beschrieben sind. Ergänzend stellt der Referent ausgewählte benutzerdefinierte Ado-Programme vor, die bei der Erstellung von Grafiken unterstützen.
Referent
Dr. Christian Brzinsky-Fay
Dr. Christian Brzinsky-Fay ist seit März 2022 bei DPC Software tätig und engagiert sich mit großer Leidenschaft für die Durchführung von Stata-Schulungen. Sein Weltbild wurde maßgeblich von Monty Python geprägt.
Er studierte Politikwissenschaft an der Freien Universität Berlin und promovierte im Bereich Sozialpolitik an der Universität Tampere in Finnland. Als quantitativer Sozialforscher nutzt er Stata seit 25 Jahren für statistische Analysen. Darüber hinaus lehrt er Statistik und empirische Methoden der Sozialforschung an der Universität Hamburg.
Program
Asjad Naqvi (Österreichisches Institut für Wirtschaftsforschung (WIFO))
Abstract: When working with flow data in Stata, such as trade, financial transactions, or migration, we often encounter limitations in visualizing network structures. To address these challenges, this presentation introduces and showcases a set of tools for working with relational data in Stata. These tools can enable users to visualize and communicate metrics such as concentration, asymmetries, and other structural patterns embedded in flow relationships.
Derya Uysal (LMU Munich), Tymon Sloczyński (Brandeis University), and Jeffrey M. Wooldridge (Michigan State University)
Abstract: We introduce drlate, a new Stata command for estimating local average treat ment effects (LATE) and local average treatment effects for the treated (LATT) using doubly robust and covariate- balancing methods. The command complements Stata’s lateffects by expanding the set of available estimators and improving inference.
drlate implements regression adjustment, inverse probability weighting (IPW), IPWRA, AIPW, and normalized versions of IPW and AIPW estimators. Outcomes may be continuous, binary, or count. The treatment is binary (with extensions to continuous treatments under development), and the instrument is binary.
The instrument propensity score can be estimated either by maximum likelihood or by method-of-moments approaches that directly balance covariates. We implement covariate balancing propensity scores (Imai and Ratkovic, 2014) and inverse probability tilting (Graham, Pinto, and Egel, 2012, 2016) as covariate-balancing alternatives to likelihood based estimation.
In addition, we provide testing procedures for equality of LATE and LATT and for comparisons between LATE and both linear and nonlinear IV estimators. We also address an issue in the standard error calculation of lateffects and provide consistent variance estimation for all implemented estimators.
Andrei Sirchenko (Nyenrode Business University)
Abstract: We describe a new Stata command classify that computes various measures of association and correlation between two categorical variables (dichotomous and polytomous, nominal and ordinal), diagnostic scores of probabilistic forecasts of such variables, and various measures of the accuracy of deterministic forecasts of them. We compiled a comprehensive catalogue of over 200 measures of association, correlation and forecast verification and diagnostic scores for probabilistic forecasts from different fields, along with the terminological synonymy and bibliography associated with them. In addition to the overall measures, the command computes the class-specific metrics as well as their macro and weighted averages.
Wolfgang Langer (Martin-Luther-University Halle-Wittenberg)
Abstract: Since version 15 Stata offers the possibility to estimate Latent Class Models for categorical observed indicators being dichotomous, ordinal or nominal. It also integrates manifest covariates to predict the class membership of the observations. Both parts of the model, the measurement one and the prediction one, are estimated simultaneously, so that changes in the measurement part influence the estimates of the structural part and vice versa. According to Hayduk (1996) and Bakk & Kuha (2020) I propose a 3 steps approach. Firstly I estimate a sequence of Latent Class Models identifying the most appropriate solution by the entropy criteria. Secondly I analyze profile plot of the item probabilities to attach meaningful labels to the latent classes. The assignment of observations to the discrete latent classes follows the highest probability rule. Thirdly I estimate a multinomial logit regression model to predict the discrete latent class membership by exogenous level 1 and level 2 variables. To estimate a logistic intercept-as-outcome model I use the Stata xtmlogit command introduced by version 17. I demonstrate the usefulness of this approach presenting a latent class analysis of attitudes towards vaccination at the eve of the Covid 19 pandemia using the Special Eurobarometer 488 data set. Being a vaccination supporter, a conspirator or a naif is predicted within 28 European countries by the personal characteristics of the respondents and between countries by their fixed effect dummy variables. To enlighten these black boxes I estimate a random-effect intercept-as-outcome multinomial logit model with the xtmlogit command using exogenous level 2 variables like collective level of trust in government, gdp, poverty rate and the Global Health Security Index in addition. Finally I discuss the
main results and give some methodological considerations.
Philippe van Kerm (University of Luxembourg)
Abstract:This presentation will introduce and illustrate the use of the Shapley–Owen value in an array of applications. It will first introduce the concept of the Shapley value and the related concept of Owen value. It will then describe the ’shapowen‘ package, a generic calculator for the Shapley-Owen value. A range of examples will then show the practical implementation of the Shapley-Owen value in regression analysis and will illustrate a range of possible alternative uses of the Shapley-Owen drawn from income distribution research.
Ben Jann (University of Bern)
Abstract: In this talk I will present the crosswalk command, a data management utility for fast table-based recoding. The command comes with predefined crosswalk tables for common recoding tasks related to occupational classifications, e.g. to translate ISCO codes (International Standard Classification of Occupations) into ISEI scores (International Socio-economic Index of Occupational Status), OEP scores (Occupational Earning Potential), or ESeC classes (European Socio-economic Classification). However, it is also easy to define, manipulate, and apply custom recoding tables. In the talk I will briefly explain how crosswalk is implemented, present its syntax, and then illustrate its use with some applied examples.
Felix Bittmann (LIfBI, Bamberg)
Abstract: Estimating treatment effects with cross-sectional data is one of the most widespread approaches in empirical research. Provided that researchers are able to measure all relevant control variables, it is possible to approximate unbiased (causal) treatment effects. To this end, Stata offers a wide range of standard and user-written commands. Naturally, the question remains which of these methods is most robust for producing unbiased point estimates and valid inference. We address this question by evaluating 14 different commands in a comprehensive simulation study. Using four different settings (unbiased, biased, incorrect functional form, heterogeneous treatment effects), we analyze a variety of empirically relevant scenarios. Our results indicate that linear (OLS) regression exhibits the lowest bias, the smallest standard errors, and the most accurate coverage in almost all simulation specifications. Entropy balancing and some matching approaches offer advantages when nonlinearities are incorrectly specified. When heterogeneous treatment effects are present, regression adjustment or AIPW approaches deliver the best results. Surprisingly, several methods deviate substantially from the target estimands, even in unbiased “best-case” scenarios.
Daniel C. Schneider (MPIDR, Rostock)
Abstract: In Schneider (2025), a new Mata library called blockops was introduced. The library serves two main purposes. First, it provides a simple approach for working with a particular class of sparse matrices: Submatrices consisting entirely of zeros are represented by null pointers and are excluded from arithmetic operations. Second, it allows the application of built-in, (official) Mata library, or user-defined functions to each submatrix, in a manner similar to, for example, R’s apply() family of functions. This presentation revisits the core ideas underlying blockops and then outlines recent developments. Key efficiency concerns have been addressed, and numerous new methods have been added to the library’s central object, which represents a block matrix. The practical usefulness of the extended functionality is illustrated through several examples.
Meghan Cain (StataCorp LLC.)
Abstract: This talk introduces meta psycorr, a new command in StataNow for psychometric meta-analysis. Psychometric meta-analysis provides a more rigorous framework than traditional meta-analysis by correcting for statistical artifacts—including measurement error, range restriction, artificial dichotomization, and small-study bias. In this talk, we will introduce the theory and then demonstrate a practical Stata workflow. We will also generate corrected forest plots and explore heterogeneity using Stata’s integrated meta suite.